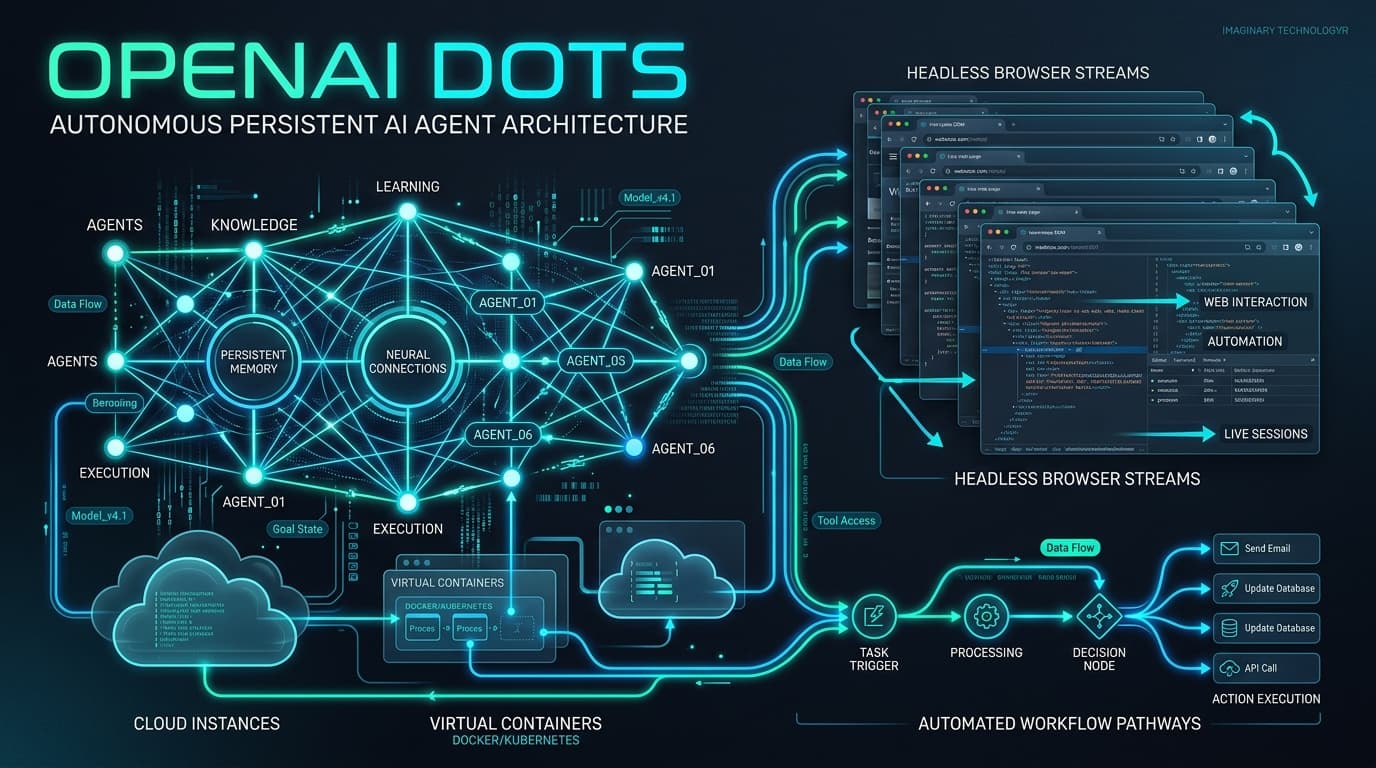
Inside OpenAI Dots: Architecture of Persistent Autonomous Cloud Agents
A deep architectural breakdown of OpenAI Dots—always-on autonomous agents powered by GPT-6 Astra with dedicated cloud containers, browser control, and enterprise plugins.
Deep technical analyses, reproducible hardware benchmarks, and production post-mortems written by principal engineers.
A deep architectural breakdown of OpenAI Dots—always-on autonomous agents powered by GPT-6 Astra with dedicated cloud containers, browser control, and enterprise plugins.
A deep architectural breakdown of OpenAI Dots—always-on autonomous agents powered by GPT-6 Astra with dedicated cloud containers, browser control, and enterprise plugins.
How modern cloud databases decouple leader election from replication quorums across US, UK, EU, and APAC regions to cut p99 write commit latency by 54%.
A deep engineering breakdown of virtualized HBM3e memory paging, prefix tree sharing, and decoupled prefill-decode clusters for high-throughput AI inference.
Why traditional epoll and work-stealing async runtimes hit a wall at 100GbE line rates, and how shared-nothing io_uring ring buffers eliminate syscall overhead.
Frontier LLM inference engines, GPU kernel optimization, disaggregated KV-cache architectures, and production ML systems.
Multi-region distributed consensus, cloud-native networking, Kubernetes scheduler internals, and high-availability infrastructure.
Memory-safe systems programming in Rust, Linux kernel asynchronous I/O, lock-free data structures, and performance engineering.
Filter peer-reviewed essays by architecture domain or sort by reading depth.
A deep architectural breakdown of OpenAI Dots—always-on autonomous agents powered by GPT-6 Astra with dedicated cloud containers, browser control, and enterprise plugins.
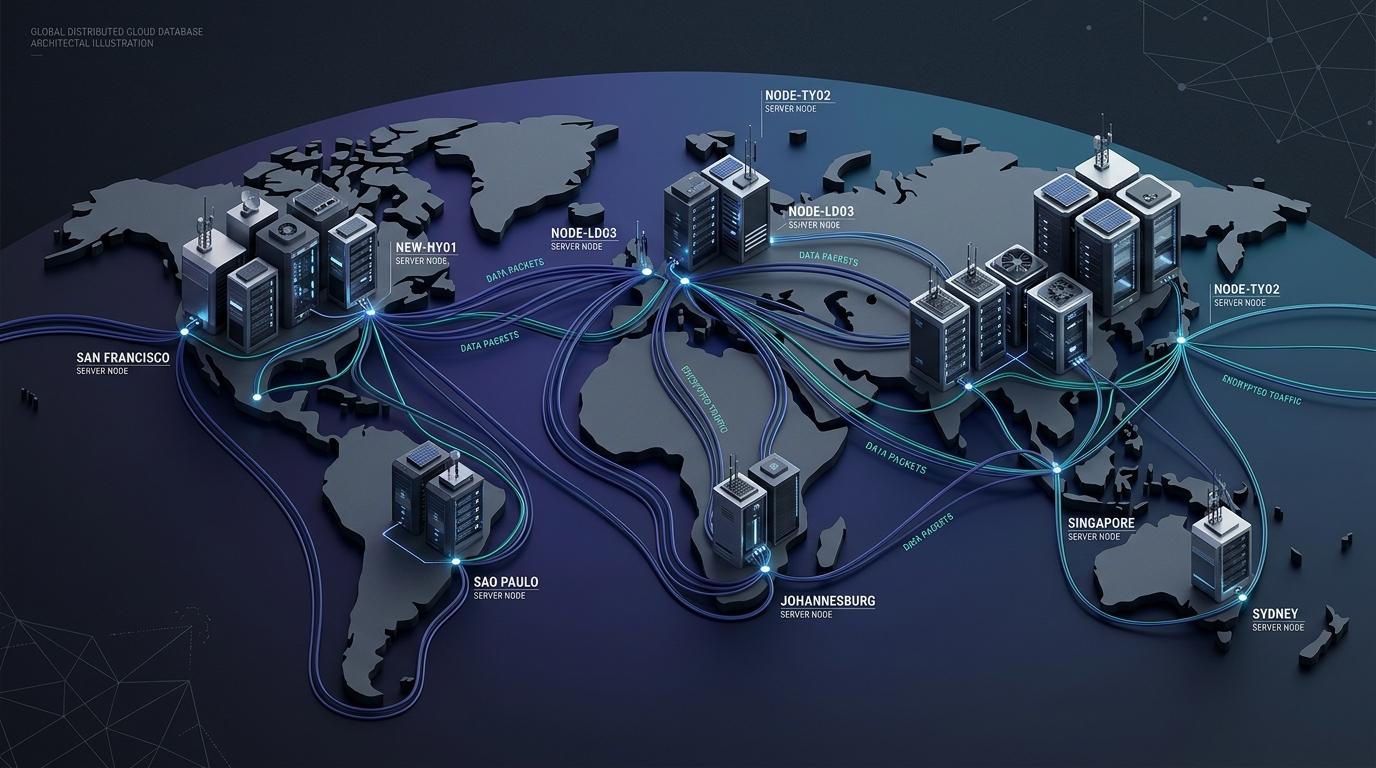
How modern cloud databases decouple leader election from replication quorums across US, UK, EU, and APAC regions to cut p99 write commit latency by 54%.
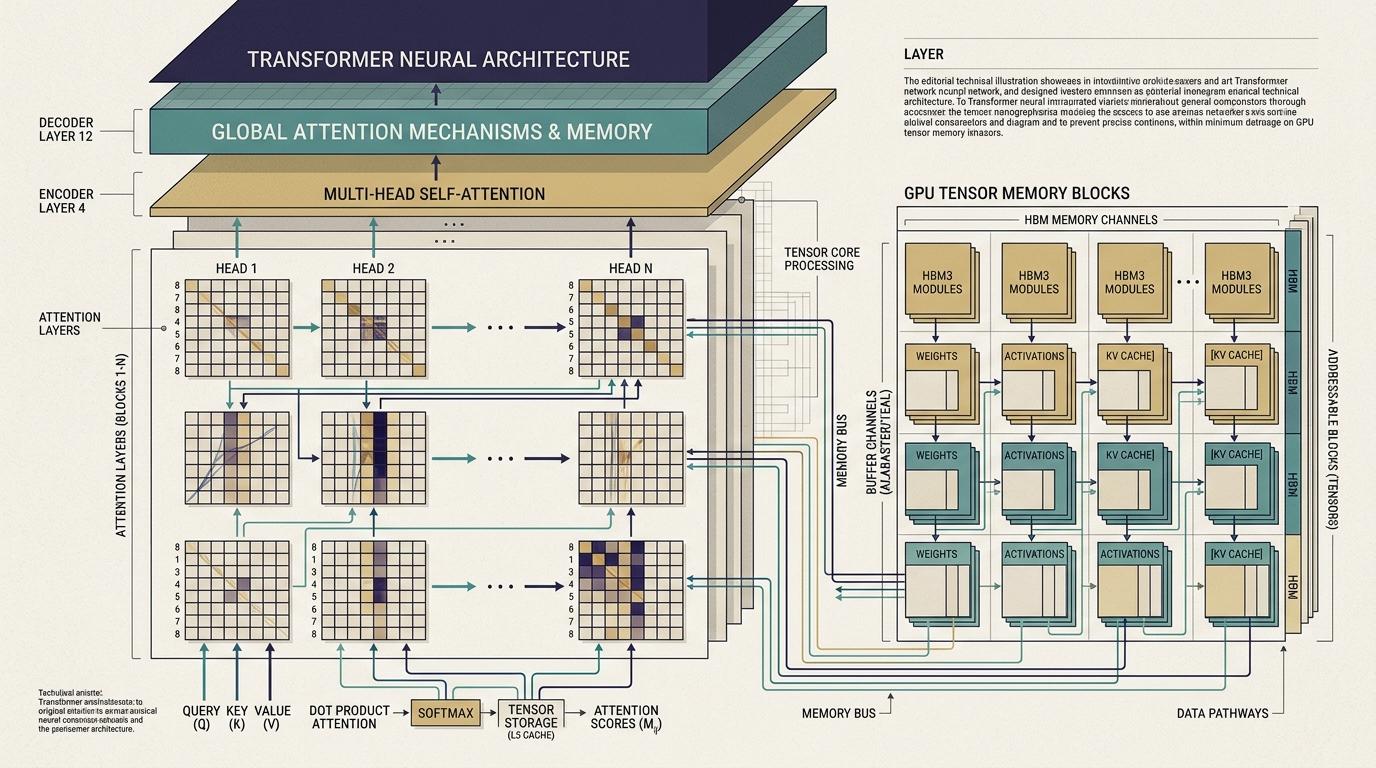
A deep engineering breakdown of virtualized HBM3e memory paging, prefix tree sharing, and decoupled prefill-decode clusters for high-throughput AI inference.
Why traditional epoll and work-stealing async runtimes hit a wall at 100GbE line rates, and how shared-nothing io_uring ring buffers eliminate syscall overhead.